Curtlycurtly.devSaaS · live
An LLM gateway that makes AI apps cheaper to run
Curtly sits between an app and its model provider. It compresses prompts and trims model output before anyone pays for the tokens, and developers switch it on with two lines of code.
- average input reduction
- 58.2%average input reduction
- added latency
- < 2 msadded latency
- compatible providers
- 15+compatible providers
- Streaming proxy for OpenAI and Anthropic compatible endpoints
- Prompt compression that leaves code blocks and JSON untouched
- API keys, usage metering and a developer console
- Subscription billing with Dodo Payments and Whop
- Marketing site, public docs, OpenAPI spec and llms.txt
Next.jsTypeScriptSupabaseDodo PaymentsResendVercel
Visit curtly.dev
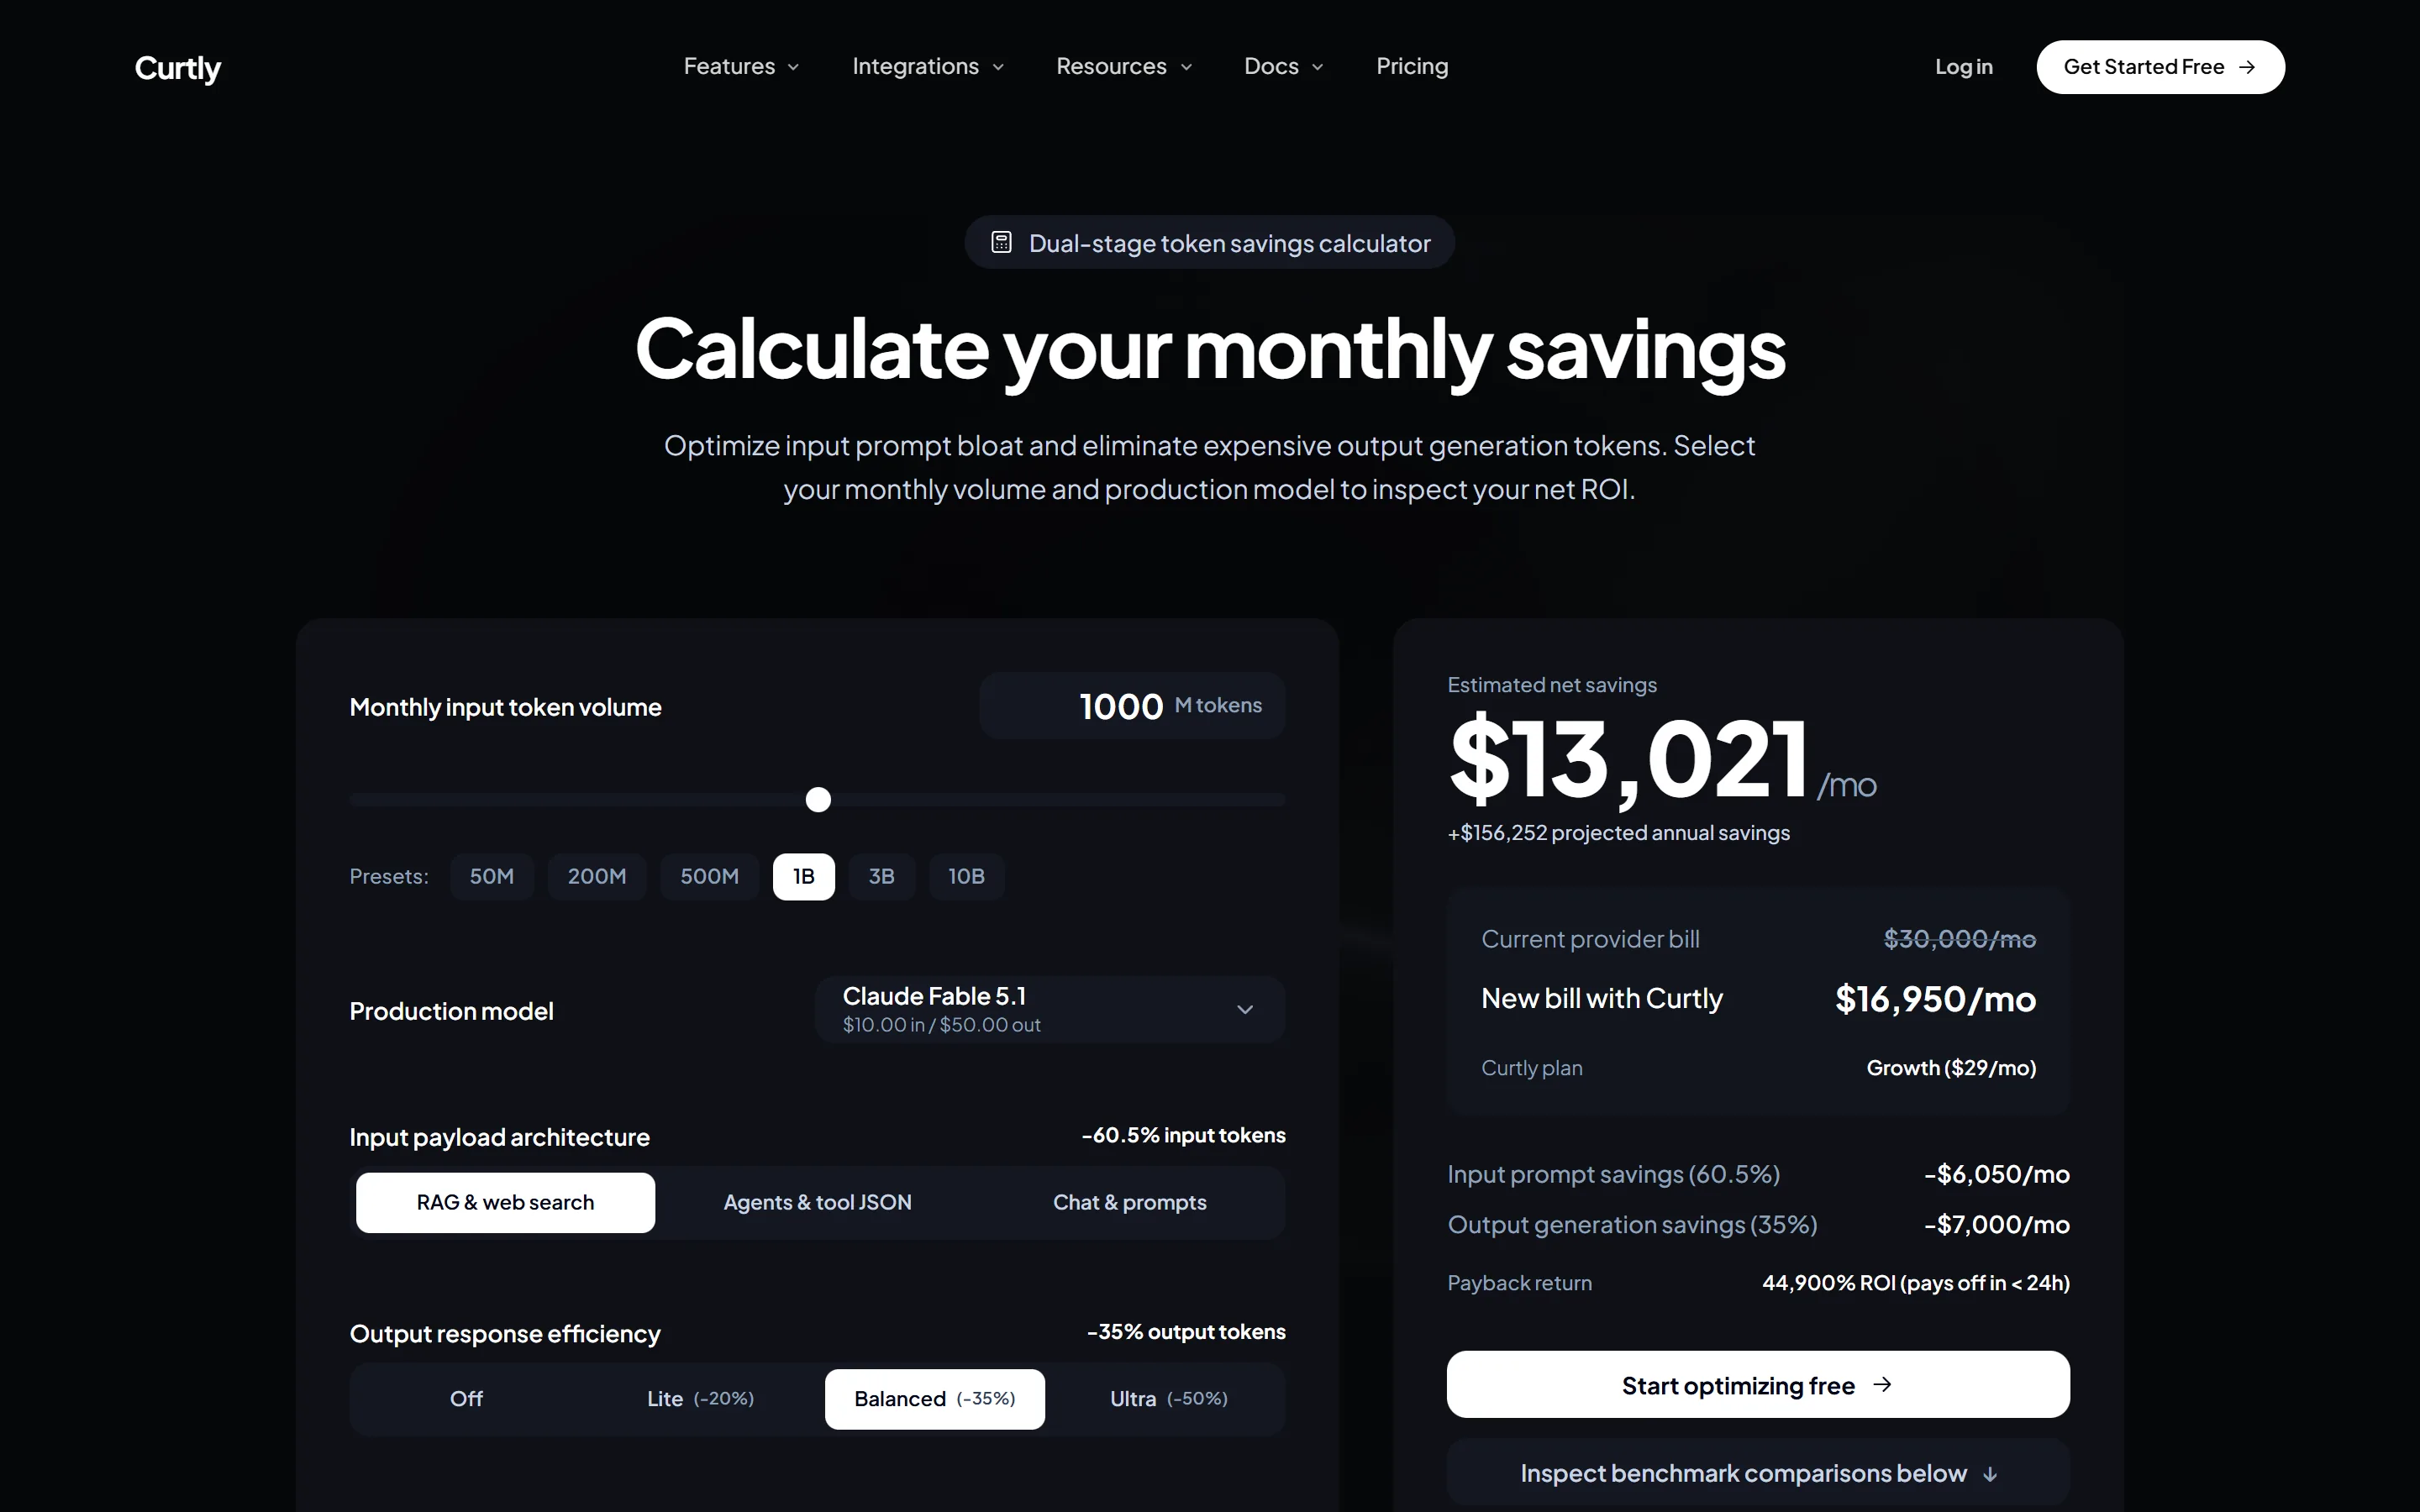 Savings calculator
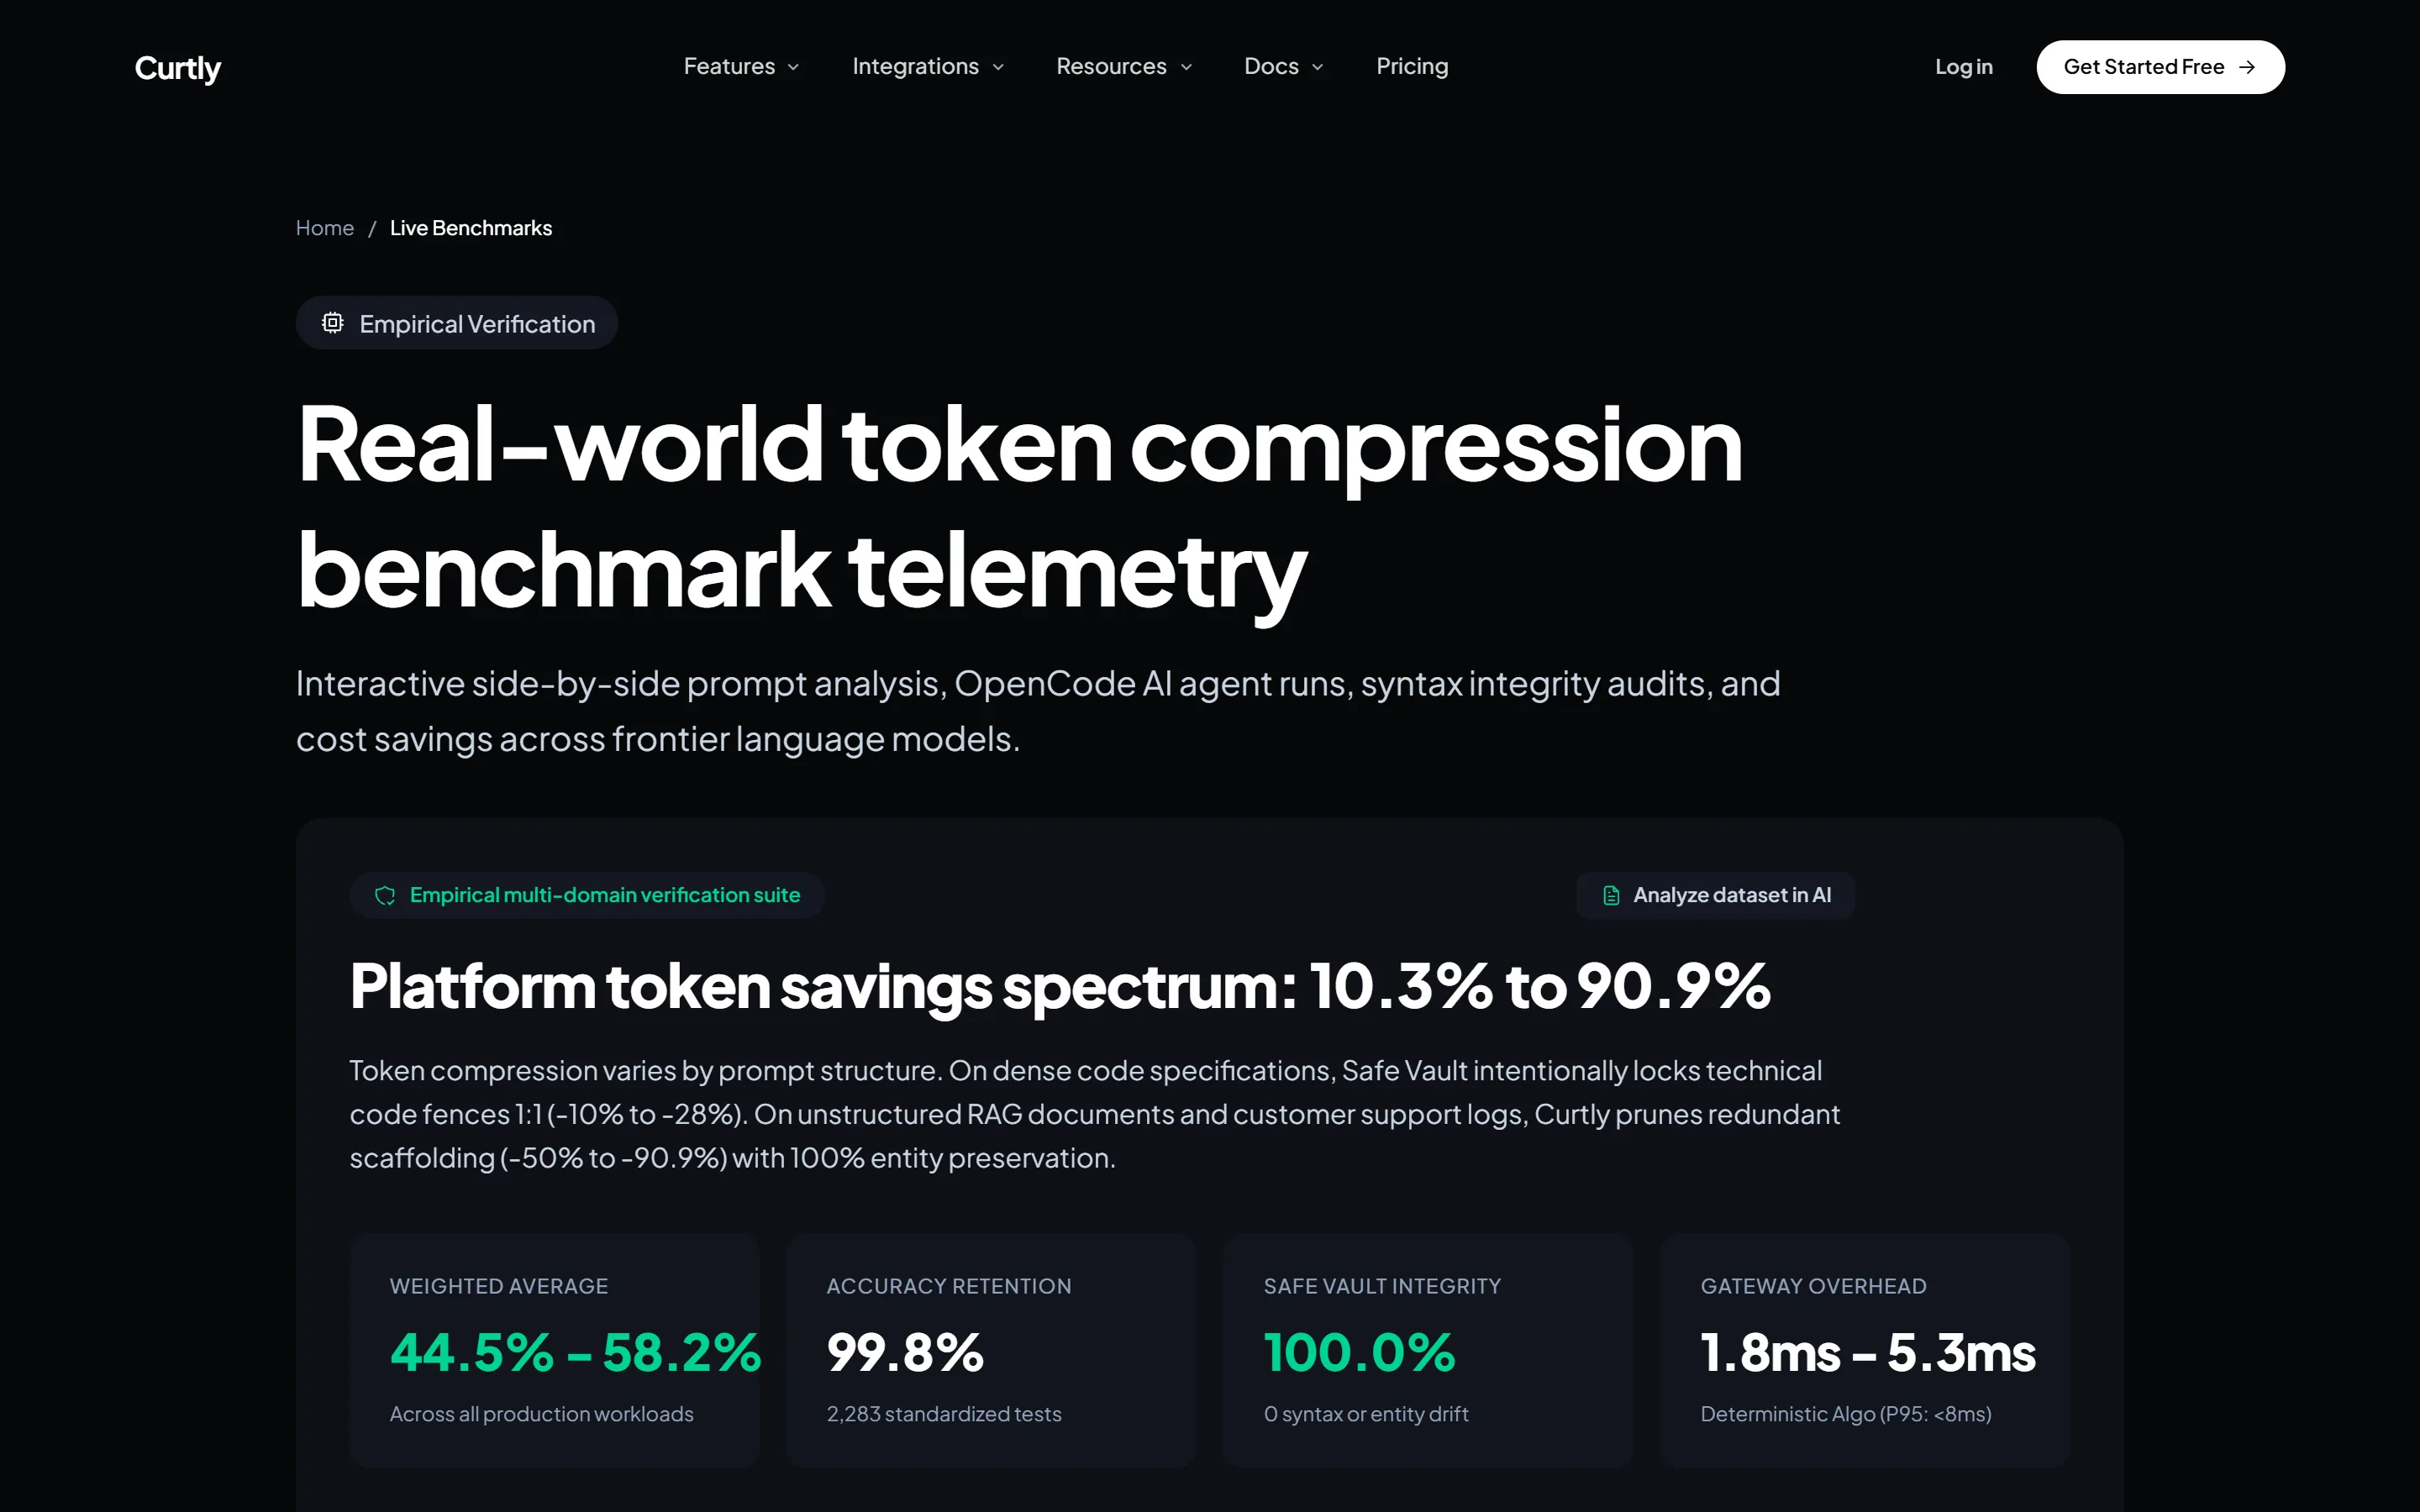 Live benchmarks
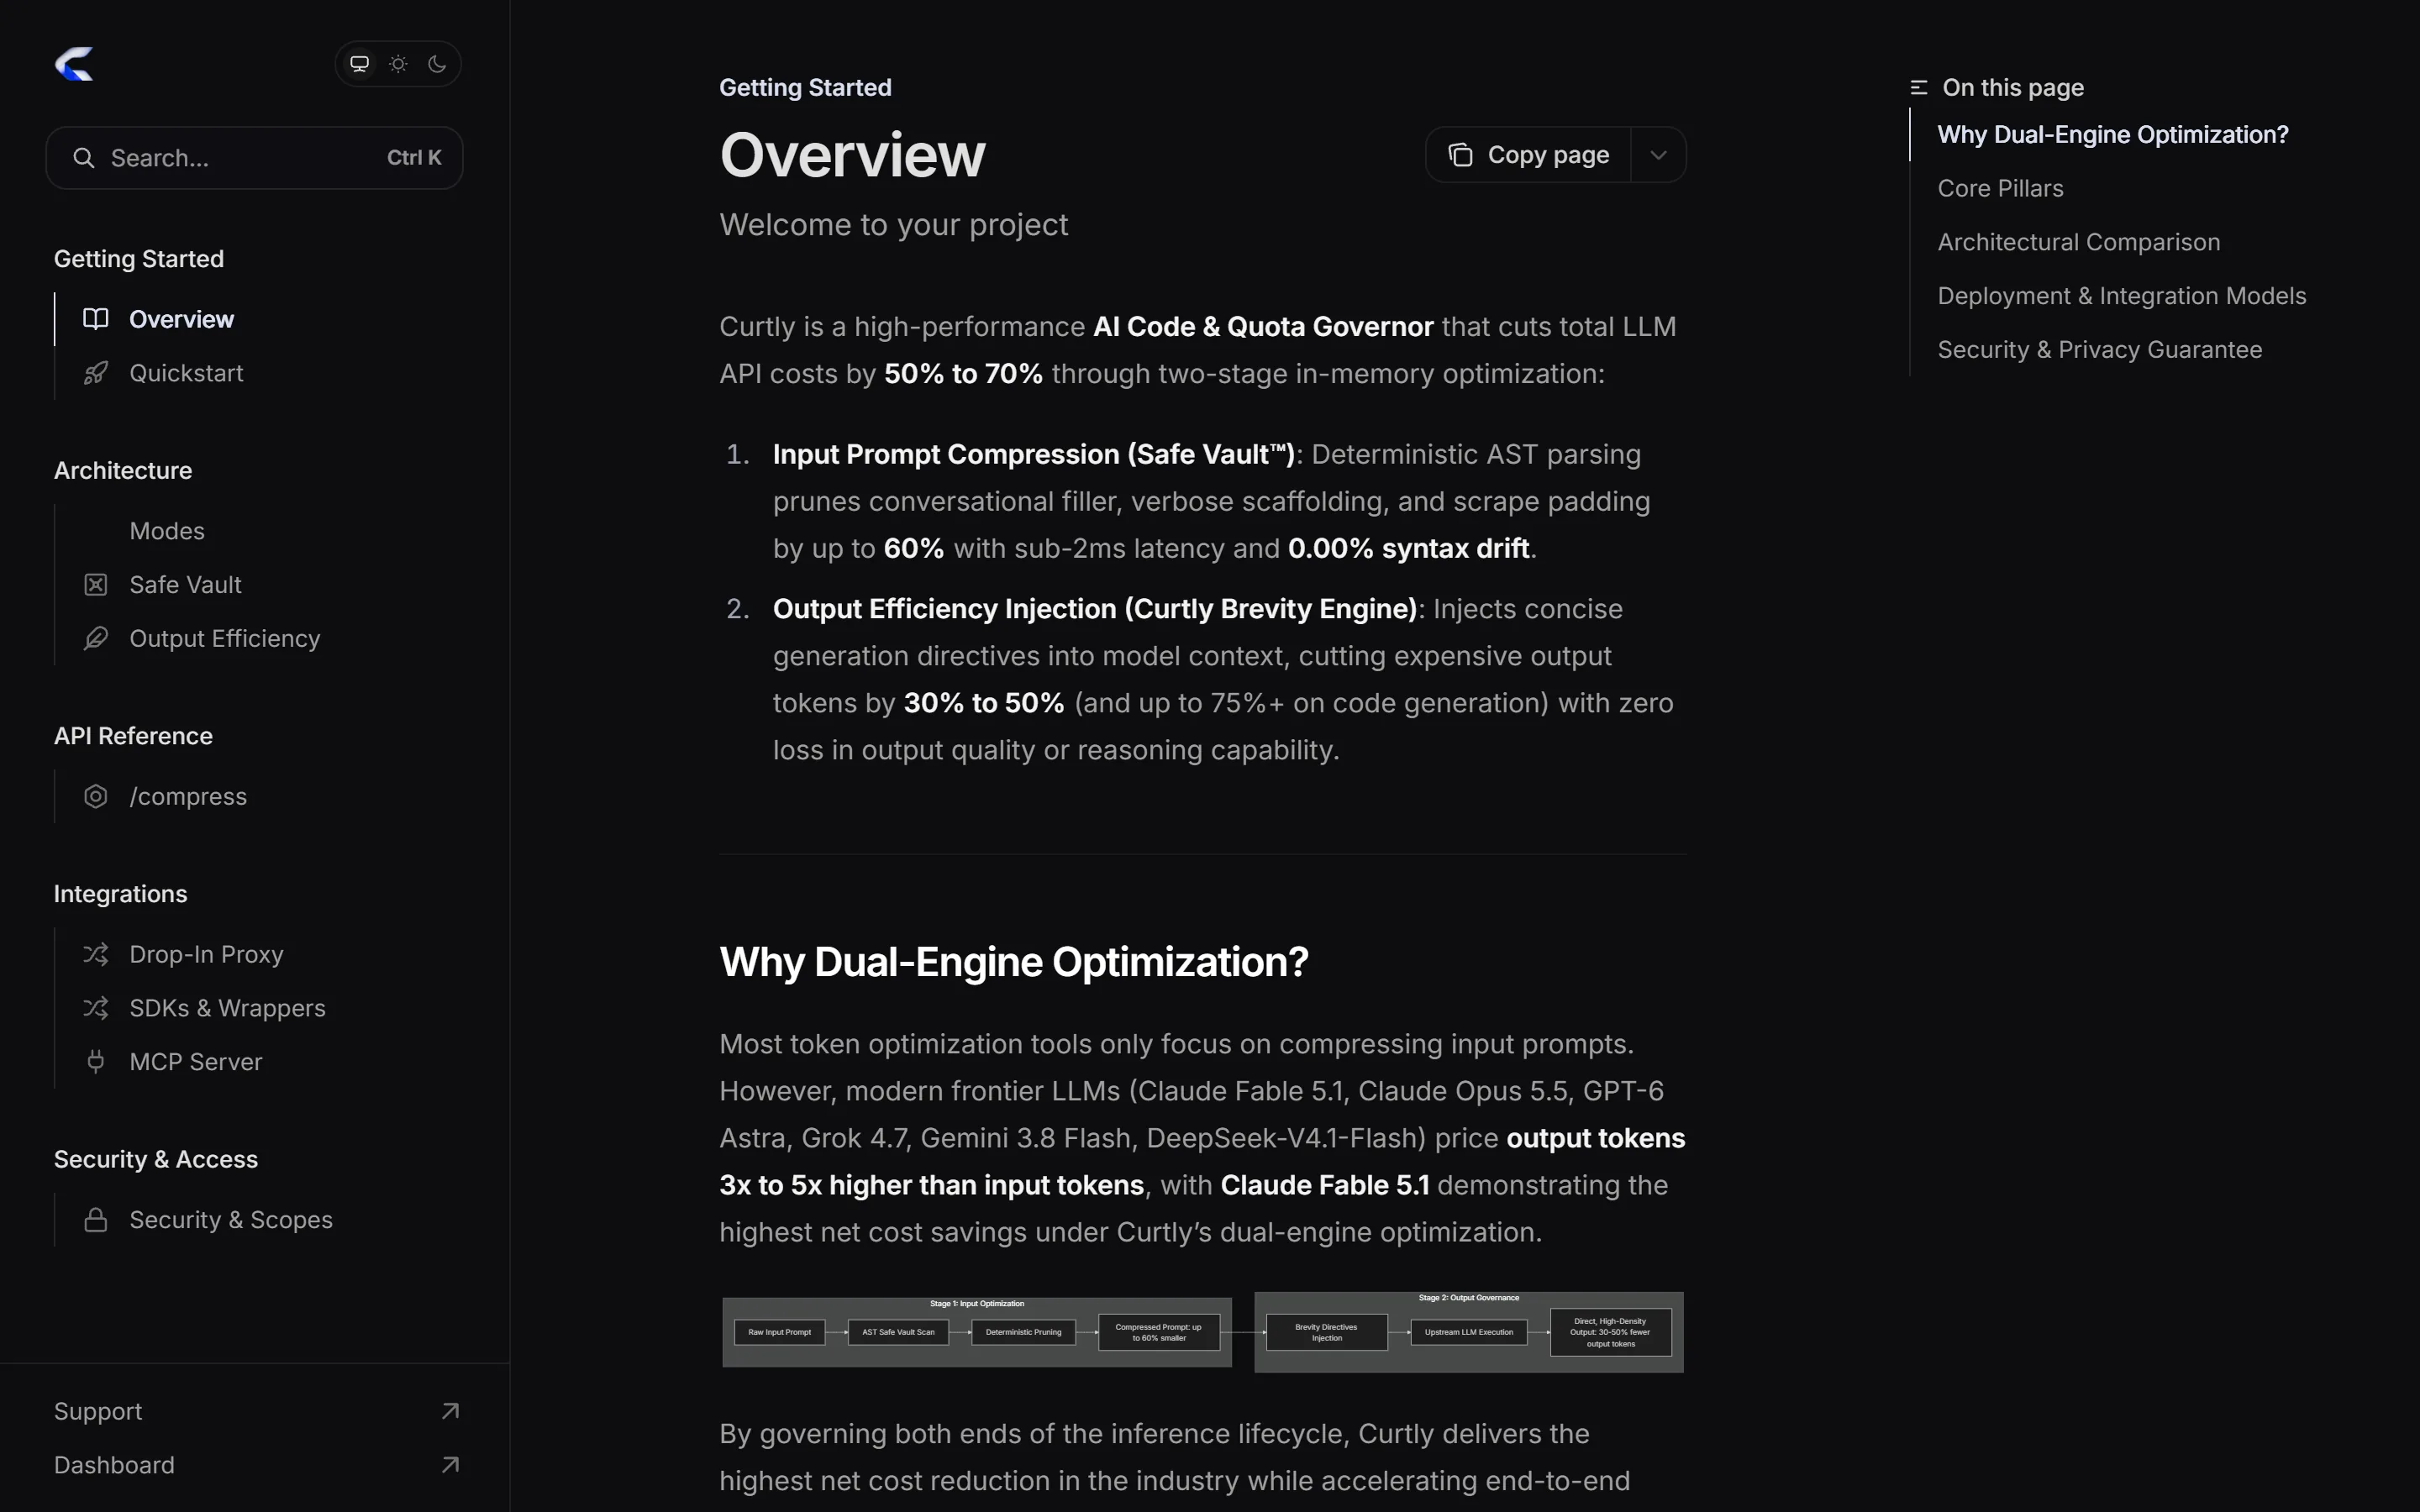 Developer docs